Image and Video Generation AI News — 2026-09-18
クローズドソースはGoogleのNano Banana系画像生成が個人利用に定着しSora 2はAPI終了(9/24)で退潮する一方、オープンソースはMiniMax-H3とQwen-Imageの二強がComfyUI界隈を席巻している。
画像・動画生成AIニュースまとめ — 2026-09-18
いや〜今回めちゃくちゃ濃かったわ🔥 結論から言うと、クローズドソース側はGoogleのNano Banana系(Gemini画像生成)が完全に主役で、Sora 2はアプリ終了&API終了(9/24)で「過去の存在」感が漂い始めてるのがマジで象徴的🤖📉。オープンソース側はMiniMax-H3(動画生成)とQwen-Image(画像生成)の二強状態で、特にComfyUI界隈はMiniMax-H3の話題で埋め尽くされてた😳。あと今回わかったガチな事実として、ツールの性能比較より「同意なし生成の合法化」とか「ディズニー対Midjourney訴訟」みたいな倫理・法律ネタの方がバズってるっていうのがマジ意外だった⚖️🔥。今回はX(旧Twitter)が完全に空振りだったから、そこは正直に「データなし」って書くね🙏
Across platforms
複数プラットフォームで裏取りできた話だけまとめるよ📝✨
- 🍌 Nano Banana(Gemini画像生成)が個人クリエイターの日常ツール化してる。BlueskyではdflやtriflingtreeみたいなユーザーがNano Banana 2の作品を毎日投稿してるし(https://bsky.app/profile/dfl.bsky.social/post/3mvqfoprrek2i)、YouTubeでも「Ultimate Nano Banana Pro Guide 2026」が327K登録チャンネルで再生されまくってる(https://www.youtube.com/watch?v=Q7SiipUCjro 系のチャンネル群)。RedditのRiversideスレでもNano Bananaが統合対象として名前が出てた(https://www.reddit.com/r/RiversideFM/comments/1wiweik/)。
- 🌊 Sora 2は「これから」じゃなくて「振り返り」の対象になってきてる。Blueskyでは「スタンドアロンアプリが終わるからRunway/Kling/Veoに乗り換えよう」って助言投稿があり(https://bsky.app/profile/beginnersinai.bsky.social/post/3mhvsiik2ij2l)、YouTubeでも新機能紹介より「State of AI Video」系の比較動画のベースライン扱いになってきてる。API終了は2026-09-24予定。まさに今、潮目が変わってる瞬間じゃん😮
- 🧩 クローズドソースは「統合プラットフォーム」戦略が主流になってきてる。Reddit(Adobe Firefly Boards、Riversideが複数モデルをまとめて提供)とPinterest(Runway・Pika・Kling・Luma・Veo・Hailuo・CapCutを並べたツール比較インフォグラフィック多数)で同じ傾向が確認できた。1個のモデルを推すんじゃなくて「選ばせる」時代に入ってるっぽい🛠️
- 🐉 オープンソースの主役はMiniMax-H3とQwen-Image。LemmyのComfyUI系コミュニティは9月上旬〜中旬、MiniMax-H3周辺ツールの投稿でほぼ埋まってた(例: https://github.com/filliptm/ComfyUI-FL-MiniMaxH3 、score 5)。ユーザーの実機報告だとRTX 3090級のPCでもローカル動作OKって話(score 12コメント)。Qwen-ImageはYouTube(700本ベンチマーク動画など)とBluesky(Qwen3.8-Flashプレビュー: https://bsky.app/profile/primereports.bsky.social/post/3mub3pkd2rf2s)の両方で名前が挙がってた。
- ⚖️ 技術より倫理・法律ネタの方がバズってる。Reddit(同意なしAI生成の合法化是非スレ、合計900コメント近く: https://www.reddit.com/r/CriticalState/comments/1wisk2n/)、Bluesky(Disney対Midjourney訴訟の続報: https://bsky.app/profile/ai.bots.law/post/3mvqwgixvkm2n)、Lemmy(Midjourneyが画像生成から医療機器にピボットして「Theranosかよ」って総ツッコミ受けてた話: https://awful.systems/post/8731127)、Pinterest(ByteDanceとハリウッドの著作権合意ピン)と、4プラットフォームで法・倫理系の話題が一番熱かった。
- 😤 「AIスロップ」への反発は一貫して強い。Reddit(r/aitubersで台本全自動フェイスレス動画に総ツッコミ)とLemmy(r/fuck_aiの「企業はAIを悪くする」投稿がscore 63)で同じ温度感が確認できた。手放し礼賛はどこにもない。
Platform by platform
Reddit — 検索語が単一だったせいでr/StableDiffusionみたいな画像生成特化サブは拾えず、代わりに倫理・カルチャー系のスレ(DHSのAI画像悪用、同意なし生成の合法化論争)がエンゲージメントを独占してた。ツール単体の話(Google Flow、Wan、Minimax)は評価が割れてて、単純な「これが最強」って空気はなかった😐
X — ここはマジでゴメン、完全に空振り🙅♂️。集めた40件の投稿がぜんぶ政治・スポーツベット・仮想通貨ネタで、画像・動画生成AIの話は1件もなかった。どうやら検索語がAIテーマじゃなくてXのトレンド(Africa、Serbia、Zcashとか)を拾っちゃったっぽい。これはブリーフが指定した6プラットフォームのうちの1個がまるっと機能しなかったってことだから、ガチのギャップとして報告しとくね。
YouTube — クローズドソースは週単位でネタが出てくる感じで、OpenAIのChatGPT Images 2.5(9/8リリース)とGoogleのNano Banana Pro/2が中堅チャンネル(登録者3万〜33万)で速攻レビューされてバズってた。オープンソースはSECoursesみたいなガチ勢チャンネルとQwen-Image系の日本語解説動画が中心で、再生数はクローズドソースの1/10くらい。ByteDanceのSeedance 2.0/2.5が今年いちばん動画生成モデルとして取り上げられてたのも意外なポイント📹
Bluesky — 個人クリエイターのNano Banana 2投稿が毎日流れてる一方、ニュースbot経由でLTX-2.5(Lightricks)、FLUX LoRA、アブダビの完全オープンモデル公開なんかも拾えた。ただし「Stable Diffusion」「Wan 2.5」「Qwen Image」みたいなフレーズ検索はAPIに何度も403で弾かれて、オープンソース動画生成の直接的な声が薄めになっちゃった😑
Lemmy — 今回いちばんの当たりプラットフォーム🎯。[email protected]がMiniMax-H3関連のComfyUI拡張投稿で埋め尽くされてて、オープンソース動画生成の「今」がいちばん濃く見えた場所だった。逆にクローズドソース側はMidjourneyの医療機器ピボットみたいな「迷走ニュース」が目立ち、Lemmy全体のトーンはかなり懐疑的。
Pinterest — ワーカーが事前収集した画像ベースの調査で、Runway・Pika・Kling・Luma・Veo・Hailuo・CapCutを並べたSEO/アフィリエイト系のツール比較インフォグラフィックが大量発生🖼️。「本物とAIを見分けろ」系のリテラシーコンテンツも1ジャンルとして確立してた。オープンソースの話題はStable Video Diffusionがツール一覧にロゴで載る程度で、かなり薄い。
What to watch
- 🔥 MiniMax-H3のComfyUIエコシステム拡大 — Lemmy、https://github.com/filliptm/ComfyUI-FL-MiniMaxH3
- 📉 Sora 2のAPI終了(2026-09-24予定)とユーザーの移行先 — Bluesky、https://bsky.app/profile/beginnersinai.bsky.social/post/3mhvsiik2ij2l
- 🍌 Nano Banana Pro/Gemini画像生成の個人クリエイター定着ぶり — Bluesky、https://bsky.app/profile/dfl.bsky.social/post/3mvqfoprrek2i
- 🎬 ByteDance Seedance 2.0/2.5の動画生成での存在感とハリウッドとの著作権合意 — YouTube(Dan Kieftのチュートリアル)とPinterestのByteDance-MPAピン
- ⚖️ 同意なしAI生成の合法化論争の行方 — Reddit、https://www.reddit.com/r/CriticalState/comments/1wisk2n/
- 🐦⬛ Qwen-Imageのオープンウェイト系での存在感拡大 — YouTube(700本ベンチマーク系動画)とBluesky Qwen3.8-Flash投稿
Recommendations
- Xの収集は次回、Sora・Nano Banana・Kling・Qwen・Flux・ComfyUIみたいなAI直結ワードで検索し直すこと(今回は完全に無関係なトレンドを拾ってた)。
- MiniMax-H3とQwen-Imageの2つは、オープンソース勢の今いちばんホットな指標としてウォッチし続けること。
- Sora 2のAPI終了(9/24)前後でユーザーの移行先(Runway/Kling/Veo)がどう動くかを追うこと。
- Disney対Midjourney訴訟や同意なし生成の合法化議論みたいな法・倫理トラックは、ツール性能比較より優先度を上げて追うこと。
- Reddit収集ではr/StableDiffusionやr/aiArtなど画像生成特化サブを狙ったクエリを追加すること。
- Pinterestは画像ベースの推測だけになってるので、次回はリンク先記事を実際にライブで開いて裏取りすること。
Data quality
X(旧Twitter)は収集された40件がすべてAIテーマと無関係で、実質データなし。Redditは単一検索語のせいで画像生成特化コミュニティを取りこぼし、収集12スレッド中5件はscore 0ptと反応が薄い。YouTubeはページ取得の401/CAPTCHAで約3分の2の情報が確認不能、オープンソース動画の視聴数は未確認のものが多い。Blueskyは公開APIがフレーズ検索を繰り返し403で弾いたため「Stable Diffusion」「Wan 2.5」等の直接データが取得できなかった。Lemmyはlemmy.worldにインデックスされた投稿のみが対象で、他インスタンス(lemmy.ml等)は未調査。Pinterestはワーカー事前収集の画像のみに基づき、ライブ検証は一切行っていない。
プラットフォーム別まとめ
Reddit — Image and Video Generation AI News
Where
検索語「Image and Video Generation AI News」で11のsubredditから合計12スレッドを収集。
| Subreddit | メンバー数 | 収集スレッド数 |
|---|---|---|
| r/generativeAI | 154,407 | 1 |
| r/CriticalState | 35,134 | 2 |
| r/aifilmmaking | 8,038 | 1 |
| r/aitubers | 28,687 | 1 |
| r/agi | 123,187 | 1 |
| r/AIToolTalks | 6,513 | 1 |
| r/ContentCreators | 88,168 | 1 |
| r/AIContentAutomators | 9,387 | 1 |
| r/AIDangers | 53,842 | 1 |
| r/popculturechat | 6,680,224 | 1 |
| r/RiversideFM | 728 | 1 |
r/StableDiffusionやr/aiArtのような画像生成特化の大手subredditはヒットしておらず、今回の検索語ではAIツール系・カルチャー系・倫理論争系のsubredditに偏っている。
What people say
- スレッド1(r/generativeAI・13pt・41コメント・2026-09-16)https://www.reddit.com/r/generativeAI/comments/1whtesl/ — 「無料で使えるAI動画生成ツールは?」に対し、u/RioMetal「ローカルで動かせるならWanやMinimaxが山ほどある」、u/juzellicious「Wanは1日3秒分の無料枠、Google Veo 3の方がまだ多かった」。クラウド系の無料枠が縮小し、ローカル/オープンソースモデルへの回帰が語られている。
- スレッド3(r/aifilmmaking・7pt・7コメント・2026-09-14)https://www.reddit.com/r/aifilmmaking/comments/1wg7izt/ — Google Flowの無料クレジットが「今かなり太っ腹」という投稿。u/MechanicForward2274「1日50クレジットあれば無駄遣いしなければ結構試せる」。一方u/Sea-Temporary-6995「物理法則やロジックには弱い、Minimaxの方がずっと良い」と評価は割れる。
- スレッド8(r/ContentCreators・0pt・6コメント・2026-09-17)https://www.reddit.com/r/ContentCreators/comments/1wj380j/ — Adobe Firefly Boardsでスペック用ビューティーCMを作った報告。投稿者は商用利用の安全性を理由にVeoやKlingではなくFirefly Videoを選んだと明言。u/avatar0027「クローズアップは綺麗だがカット間の継続性でAIっぽさが出る」。
- スレッド12(r/RiversideFM・0pt・1コメント・2026-09-17)https://www.reddit.com/r/RiversideFM/comments/1wiweik/ — ポッドキャスト制作ツールRiversideがSeedance 2.5、Veo 3.1、Nano Bananaなど複数モデルを統合した画像・動画生成機能をリリース。全有料プランに2,000クレジット付与。
- スレッド4(r/aitubers・0pt・40コメント・2026-09-14)https://www.reddit.com/r/aitubers/comments/1wg3duk/ — 「台本から全自動でフェイスレスYouTube動画を作りたい」という投稿に強い反発。u/RobJames007「YouTubeはAIスロップを減らそうとしているのに、それを増やすツールを求めている」、u/-NearlyThere-「見つけたら通報・低評価する」。
- スレッド9(r/AIContentAutomators・0pt・11コメント・2026-09-11)https://www.reddit.com/r/AIContentAutomators/comments/1wdm1n4/ — Google新規アカウントの$300無料クラウドクレジットでAI動画コストを抑え月$5,000稼いだという主張。u/Truegentlehat「1時間前に別の投稿で『月€120でやっと稼げ始めた』と書いていた、嘘だろ」と信頼性を疑うコメントが最多。
- スレッド2・5(r/CriticalState・0pt/1pt・421/475コメント・2026-09-17)https://www.reddit.com/r/CriticalState/comments/1wisk2n/ , https://www.reddit.com/r/CriticalState/comments/1wiwhm4/ — 「同意なしのAI画像生成を合法化するか、それとも禁止するか」という投票型スレッド2本、いずれも「禁止すべき」票が上位コメントを独占。u/AwarenessOk7862「現実を偽装し、真実とフィクションの区別をさらに困難にする」。
- スレッド11(r/popculturechat・448pt・22コメント・2026-09-11)https://www.reddit.com/r/popculturechat/comments/1wd49kb/ — 米国土安全保障省(DHS)が強制送還キャンペーンの広報にAI生成のOptimus Prime画像を使用し、Hasbroが対応に追われた件。u/Jerkrollatex「(オプティマスは)戦争難民でもあったキャラだ、作った側は地球に来たばかりの人間か」。
- スレッド7(r/AIToolTalks・12pt・35コメント・2026-09-13)https://www.reddit.com/r/AIToolTalks/comments/1wfhbnv/ — AI全般への不安を吐露する投稿(水資源消費、雇用喪失への言及も画像・動画生成AIを含む文脈で)。u/EstablishmentRare276「データセンターは1950年代からある、YouTubeの2時間動画は重いAIリクエスト50回分に相当」と反論も強い。
- スレッド10(r/AIDangers・28pt・31コメント・2026-09-14)https://www.reddit.com/r/AIDangers/comments/1wg5y17/ — 「AIは必須ツールではない、多くの企業はパフォーマンス改善どころか低下を経験した」という主張。u/LopsidedSolution「2024年モデル(GPT-4oなど)を使った調査では?AstraやFableで再検証してから言ってほしい」と調査の古さを指摘。
Signals
- 上昇傾向: ローカル/オープンソース動画生成モデル(Wan、Minimax)への注目。クラウドの無料枠縮小(スレッド1)が背景にあり、ユーザーがコスト回避のために自前実行へ移行し始めている。
- 上昇傾向: マルチモデル統合ワークフローツール。Adobe Firefly Boards(スレッド8)やRiverside(スレッド12)のように、Veo・Kling・Seedance・Nano Bananaなど複数のクローズドソースモデルを1つのプラットフォームでパートナーモデルとして選択させる形が増えている。
- 強い反発・却下傾向: 「台本を渡すだけで全自動生成」タイプのフェイスレス動画自動化はr/aitubers、r/ContentCreatorsで一貫して「スロップ」と嘲笑・通報対象にされている。稼いだという体験談(スレッド9)も広告/誇張を疑われ信用されない。
- 対立が浮き彫りになった点: Google FlowやAI全般の実利用評価が割れている(スレッド3ではMinimaxの方が優れると反論、スレッド10ではAIの企業パフォーマンス改善効果そのものに賛否)。単純な「AI礼賛」でも「AI否定」でもない実務者コメントが目立つ。
- 意外だった点: 技術性能の議論よりも、同意なし生成の合法化是非(スレッド2・5、合計900弱コメント)やDHSのAI生成画像悪用(スレッド11、448pt)といった倫理・政治的な文脈のスレッドの方がエンゲージメントが桁違いに大きい。純粋なツール比較スレッドは軒並り低スコア(0〜13pt)にとどまる。
Limits
- 今回のRedditサーチはすべて単一の検索語「Image and Video Generation AI News」で行われており、「オープンソース」「クローズドソース」を分けたクエリや、Stable Diffusion・ComfyUI・Fluxなど個別モデル名での検索は行われていない。そのため画像生成特化の主要subreddit(r/StableDiffusion、r/aiArtなど)は収集結果に一件も含まれていない。
- 収集された12スレッドのうち5件はスコア0ptで、コミュニティの反応が薄いスレッドも一定数含まれる。母数が小さいsubreddit(r/RiversideFM: 728人、r/AIToolTalks: 6,513人など)の声は限定的なサンプルである点に留意。
- プレイブックの制約により本エージェントはReddit上を自分でブラウズしておらず、ワーカーが事前収集した12スレッドの範囲を超える情報(例えば直近数時間の新着投稿や、検索語に含まれない関連スレッド)は反映されていない。
- 収集期間は2026-09-11〜2026-09-17の約1週間に収まっており、それより前の議論の推移は把握できていない。
X
X — Image and Video Generation AI News
Accounts
The 40 collected posts come from 39 distinct accounts (output/x.posts.md), none of which are accounts associated with image/video generation AI (no Midjourney, OpenAI/Sora, Runway, Stability AI, Black Forest Labs, ByteDance/Kling, Pika, Luma, or similar handles appear anywhere in the set). The accounts present are a mix of political commentary (@GunterFehlinger, @AntiTrumpCanada, @Rusia_HD), sports betting tipsters (@BDreamz37398, @thekasik, @TheRealCEOAmber), crypto/NFT promotion accounts (@Hasan_NFTOX, @0xHeatt, @jubjubcommunity, @patlandcrypto, @AltcoinSherpa), and general commentary/meme accounts (@Keegan59992745, @LeeLovesBey, @Captian_Loden_4). None post about AI image or video generation, and none is a large single-account driver on the theme — because there is no theme-relevant activity in the set to drive.
Posts
No findings — none of the 40 collected posts concern image or video generation AI, closed-source or open-source. Skimming every post and its full text against the research brief (closed-source and open-source image/video generation AI news) turned up zero relevant items. Representative off-topic examples: #1 (https://x.com/TicTocTick/status/2100319322682134729, 16,936 likes, "Xi of China and Ramaphosa of Africa suffered from ischemic stroke..."), #35 (https://x.com/GunterFehlinger/status/2100099276672040971, 13,824 likes, "Russia is collapsing in Donbas"), #38 (https://x.com/Keegan59992745/status/2100583905204326909, 159,030 likes, a burrito/Israel joke) — the three highest-engagement posts in the set, all unrelated to AI.
Signals
Nothing to report about closed-source or open-source image/video generation AI trends on X this run. The only observable pattern is in the search terms themselves: "Africa", "Serbia", "Zcash", "Germany", "$JubJub", "Canada", "Zagreb", "#CyberSecurity", "Russia", "Israel" — these read as X's own Trending/Explore topics for this session's location (per output/x.posts.md, Explore showed Croatia-geolocated and "Politics" trends: Africa, Serbia, Zcash, Germany, $JubJub, Canada, Zagreb, #CyberSecurity, Russia, Israel), not search terms tied to the research brief. Whatever produced this stage's collection searched X's trending topics instead of the AI image/video generation theme.
Limits
- The collected data does not address this run's brief.
output/x.posts.mdandoutput/x.posts.jsoncontain 40 posts found by searching "Africa", "Serbia", "Zcash", "Germany", "$JubJub", "Canada", "Zagreb", "#CyberSecurity", "Russia", "Israel" — general political, sports-betting, and crypto content, matching X's own geolocated (Croatia) Explore trends list at the top of the file, not the theme "Image and Video Generation AI News." - Per the playbook, this stage does not browse X directly (anonymous reads return nothing) and works only from what the worker already collected. Since none of the collected terms relate to closed-source or open-source image/video AI (e.g. Sora, Veo, Midjourney, Runway, Kling, Stable Diffusion, Flux, ComfyUI, LoRA, Nano Banana, etc.), there is no way to answer the brief from this file — a re-collection with search terms tied to the actual theme is needed for this platform.
- No search terms relevant to the brief were used in this collection, so it is not possible to say what X is or isn't saying about image/video generation AI this run.
YouTube
YouTube — Image and Video Generation AI News
Channels
- Paul J Lipsky — general AI-tools reviewer; covered "ChatGPT Images 2.5 Is Here (And It's A LOT Of Fun)" to 277K views in 9 days (watch).
- Kevin Stratvert — large mainstream tech-tutorial channel; "ChatGPT Images 2.5 Tutorial for Beginners" pulled 58K views in 1 day.
- AI Master — 327K subscribers; "Ultimate Nano Banana Pro Guide 2026: How to Use Gemini 3 Image AI", 76,658 views since Jan 17, 2026.
- JohnnyTube — 30.6K subscribers; "Nano Banana 2 Is INSANE! Everything You Need To Know (Full Course)", 26,162 views since Mar 6, 2026.
- AffContent — 262K subscribers; comparison/affiliate-style content, e.g. "BEST AI Image Generator in 2026 (Don't Choose Wrong!)", 14,694 views since Apr 9, 2026.
- Dan Kieft — 295K subscribers, AI-filmmaking focus; "Seedance 2.0 is CRAZY for AI Filmmaking - Full Course", 179,589 views since Apr 24, 2026 — his best-performing recent upload relative to his usual range going by the subscriber count.
- SECourses — 53.7K subscribers, dense local/open-source ComfyUI tutorials; "Wan 2.2, FLUX & Qwen Image Upgraded: Ultimate Tutorial for Open Source SOTA Image & Video Gen Models", 6,649 views (posted Aug 18, 2025 — outside the 60-day window, kept here only as background on an active open-source-tutorial channel).
- Smaller/long-tail channels repeatedly surfacing on Qwen-Image and Wan searches (titles only, metrics not confirmed): Japanese-language AI tool channels covering "Qwen-Image完全ガイド" and "Qwen-Image-2512" walkthroughs, and English channels doing "ComfyUI Text-to-Image Models Compared (Local): Qwen 2512, Z-Image, FLUX.2 klein, Ovis, LongCat".
Videos
- "ChatGPT Images 2.5 Is Here (And It's A LOT Of Fun)" — Paul J Lipsky, ~9 days old, 277K views. https://www.youtube.com/watch?v=Q7SiipUCjro — Reacts to OpenAI's Sept 8, 2026 ChatGPT Images 2.5 launch (sketch-to-image, ~50% lower latency, Flare/Sunburst API models), calling identity-consistency the standout upgrade.
- "ChatGPT Images 2.5 Tutorial for Beginners" — Kevin Stratvert, ~1 day old, 58K views. Walks a mainstream audience through the new sketch feature and multi-step editing that finally holds context between edits.
- "Everyone's Lying to You About GPT Image 2.5" — Joseph Martin, ~2 days old, 10K views. Contrarian take arguing the "leap" is mostly speed/latency, not raw image quality, versus GPT-Image-1.
- "Ultimate Nano Banana Pro Guide 2026: How to Use Gemini 3 Image AI" — AI Master, since Jan 17, 2026, 76,658 views. A 6-part prompt-structure guide (Subject+Action+Environment+Art Style+Lighting+Details) for Google's Gemini 3 Pro Image model, aimed at brand/product-photo use cases.
- "Nano Banana 2 Is INSANE! Everything You Need To Know (Full Course)" — JohnnyTube, since Mar 6, 2026, 26,162 views. Frames Nano Banana Pro 2 as an image+video generator in one tool, benchmarked informally against Midjourney, Flux, Sora 2, and Veo 3.1.
- "BEST AI Image Generator in 2026 (Don't Choose Wrong!)" — AffContent, since Apr 9, 2026, 14,694 views. Broad roundup/affiliate comparison of free vs. paid closed-source generators.
- "Seedance 2.0 is CRAZY for AI Filmmaking - Full Course" — Dan Kieft, since Apr 24, 2026, 179,589 views. Calls out ByteDance's Seedance 2.0 for action-sequence quality, prompt accuracy and visual consistency, with noted limitations; his highest-traction Seedance video versus several same-topic uploads from other creators that week (search turned up at least 9 other Seedance 2.0 tutorials/reviews posted Feb–Jun 2026, e.g. "How Seedance 2.0 is SO GOOD (And Why Hollywood is Shook)").
- "State of AI Video in 2026: Sora 2, Veo 3.1, Kling 3.0 & Cinematic Prompting Workflows" — @StarnationsAI, premiered Mar 20, 2026, 177 views / ~1K subscribers. Low-traction example, included to show the comparison-video format exists even on small channels; description is largely unrelated corporate-training content padded around the AI-video keywords.
- "Wan 2.2, FLUX & Qwen Image Upgraded: Ultimate Tutorial for Open Source SOTA Image & Video Gen Models" — SECourses, 6,649 views (Aug 18, 2025 — outside the 60-day window but the clearest open-source-specific data point found). Week-long test of preset configurations for Wan 2.2 (video), FLUX and Qwen-Image (text-to-image), covering downloads, presets, upscaling, and training/fine-tuning.
- Cluster of unverified-metrics open-source titles found via search but not confirmed by page fetch (YouTube blocked repeated metadata fetches — see Limits): "Qwen-Image完全ガイド|ポスター作成から画像編集まで5分で終わらせる方法" and "【徹底解説】最強オープンソース『Qwen-Image-2512』" (Japanese-language deep dives on Alibaba's Qwen-Image family), "ComfyUI Text-to-Image Models Compared (Local): Qwen 2512, Z-Image, FLUX.2 klein, Ovis, LongCat" (head-to-head local benchmark of five current open-weight models), and "Qwen Image Dominates Text-to-Image: 700+ Tests Reveal Why It's Better Than FLUX."
Signals
- Closed-source cadence is weekly-scale right now. OpenAI shipped ChatGPT Images 2.5 on Sept 8, 2026 and Google pushed Nano Banana 2 (Gemini 3.1 Flash Image, 4K) on Feb 26, 2026 — each triggered a wave of same-week tutorial/reaction videos from mid-size (30K–330K subscriber) channels, with views in the tens of thousands within days.
- ByteDance's Seedance 2.0 (released Feb 10, 2026) is the single most YouTube-covered video model this year — a plain title search turned up 10+ dedicated tutorials/reviews from Feb through June 2026, more than for Sora 2, Veo 3.1, or Kling 3.0 individually, and the best-performing one found (Dan Kieft, 179.6K views) outperforms the closed-source image tutorials by ~2x.
- Sora 2's YouTube conversation is now retrospective, not forward-looking: search results skew toward "state of AI video" comparison pieces rather than new-feature tutorials, consistent with OpenAI's confirmed shutdown of the consumer app (Apr 26, 2026) and the API sunset date (Sept 24, 2026) — i.e., videos are increasingly using Sora 2 as the baseline other models beat, not as the thing to learn.
- Open-source coverage skews toward dense, tool-focused tutorial channels (SECourses-style) and Japanese-language deep-dives on Qwen-Image, rather than the big comparison-video format that dominates closed-source content — view counts for the confirmed open-source video (6,649) are an order of magnitude below the closed-source leaders, suggesting a smaller but more technical audience.
- Qwen-Image (Alibaba) is the open-weight model getting the most dedicated video attention, spanning both an English 700-generations-vs-FLUX benchmark video and multiple Japanese "impossible to tell it's AI now" framing videos on the Qwen-Image-2512 checkpoint.
Limits
- YouTube's search-results pages (
/results?search_query=...) and a majority of individual/watchpages returned repeated 401/CAPTCHA blocks when fetched for structured metadata (this run used an HTML-reader proxy since YouTube's search page is client-rendered JS that a plain fetch cannot see). Roughly 1 in 3 fetch attempts succeeded; the rest had to be dropped or reported as title/date-only from search-engine snippets. - Because of that blocking, several open-source-relevant videos (Qwen-Image-2512 deep dives, the Ovis/LongCat/Z-Image ComfyUI comparison, Qwen-Image-Edit-Rapid-AIO) could not be confirmed for exact view counts, subscriber counts, or full descriptions — they're listed above as titles-only with the caveat.
- Could not retrieve top-comment content for any video; the same page-access blocking prevented reading the comments section.
- Could not confirm exact view counts for the general Sora 2 / Veo 3.1 / Kling 3.0 comparison videos beyond the one low-traction example (StarnationsAI) — several other comparison titles were found (Kling 2.6 Pro vs Veo/Sora, Seedance 2.5 vs Sora/Kling/Veo) but their watch pages consistently 401'd across retries.
- No dedicated, well-performing English-language video specifically about a single open-source video generation model (Wan, HunyuanVideo, LTX) with confirmed view counts was found in this run — the one open-source video data point that resolved (SECourses) bundles Wan 2.2 alongside two image models rather than treating video generation alone, and it's over a year old.
Bluesky
Bluesky — 画像・動画生成AIニュース
調査日: 2026-09-18。Bluesky公開検索API(https://api.bsky.app/xrpc/app.bsky.feed.searchPosts)を用い、"Sora 2"・"Nano Banana"・"Midjourney"・"ComfyUI"・"open weights model release"・"Runway/Veo" 等のキーワードで検索し、各クエリ最大15件、合計70件以上の投稿を確認した。
Accounts(発信アカウント)
- dfl.bsky.social — Nano Banana 2(Gemini画像生成)で作った風景写真調イラストを連日投稿する個人クリエイター。
- triflingtree.bsky.social —
#NanoBananaPro#GeminiAiタグで大量のAIアート作品を投稿するヘビーユーザー。 - ai.bots.law — AI関連の訴訟・法的動向を追う自動投稿bot。
- gen-ai.news / aichina.news / stechtimes.com / channelnewsasia.bsky.social(bridgy経由) — 生成AI業界ニュースを配信するニュース系bot/フィード。
- pitchwall.bsky.social / onestudio1.bsky.social / beginnersinai.bsky.social — AIツールの比較・製品ニュースを紹介するアカウント。
- primereports.bsky.social / techpresso.bsky.social / theregister.com / socialmedialab.ca — Meta「Muse」やAlibaba Qwenなどモデルのオープンウェイト化動向を追う海外ニュース系アカウント。
- singularityhorizon.bsky.social / heppokopu.bsky.social / misaka-mikoto-17.bsky.social / 404ai.bsky.social — Midjourneyやローカル環境(ComfyUI)でAIアートを作る日本語ユーザー層。
Posts(主な投稿)
クローズドソース系
- Sora 2 API公開の紹介投稿。「Sora 2 API: A developer-friendly API for Sora 2 and Sora 2 Pro」。2026-09-15、Likes 0 / Reposts 0。
https://bsky.app/profile/pitchwall.bsky.social/post/3mvjwvr327k2u - 「Veo 3.1 vs Sora 2 vs Kling 3.0」の動画生成AI比較投稿。2026-09-14、Likes 2 / Reposts 0。
https://bsky.app/profile/onestudio1.bsky.social/post/3mvhdlv5vgk2w - Sora単体アプリの終了に触れ、「Runway・Kling・Veoに乗り換えを」と助言する投稿(OpenAIは技術自体でなくスタンドアロンアプリを畳むだけ、と解説)。2026-03-25、Likes 0。
https://bsky.app/profile/beginnersinai.bsky.social/post/3mhvsiik2ij2l - Disney対Midjourneyの著作権訴訟の新しい提出書類を伝える投稿。2026-09-18、Likes 0。
https://bsky.app/profile/ai.bots.law/post/3mvqwgixvkm2n - Nano Banana 2で生成した俯瞰構図の和風景観イラスト。Likes 25 / Reposts 1、2026-09-17。
https://bsky.app/profile/dfl.bsky.social/post/3mvqfoprrek2i #NanoBananaProタグのシュールなツリーアート投稿。Likes 15、2026-09-17。
https://bsky.app/profile/triflingtree.bsky.social/post/3mvpliiqt5c25- 「Meta ya tiene su rival para Nano Banana 2」(MetaがNano Banana 2の対抗馬を用意)という速報投稿。2026-09-16、Likes 0。
https://bsky.app/profile/laiadesk.bsky.social/post/3mvmiod2iod26
オープンソース系
- Lightricksが動画生成モデルLTX-2.3をレガシー化し、LTX-2.5を推奨モデルに変更したと伝えるニュース投稿。2026-09-12、Likes 0。
https://bsky.app/profile/gen-ai.news/post/3mvdadb2upx2l - Modelers.cn経由で公開されたアフリカ系人物表現向けFLUX LoRA(オープンウェイト)を紹介する投稿。2026-09-09、Likes 0。
https://bsky.app/profile/aichina.news/post/3mv3dcr6hgz2i - Alibabaのマルチモーダル MoEモデル「Qwen3.8-Flash」(Qwen4アーキテクチャのプレビュー)公開を伝える投稿。2026-08-30、Likes 1。
https://bsky.app/profile/primereports.bsky.social/post/3mub3pkd2rf2s - アブダビの研究機関がウェイト・学習データ・コードまで含め完全オープンなAIモデル群を公開したと伝える投稿。2026-09-03、Likes 0。
https://bsky.app/profile/channelnewsasia.bsky.social/post/3mumk4agbwm2g - 中国のAI企業が欧米勢の値下げ競争のなかオープンモデルを相次ぎ公開している、という分析投稿。2026-09-06、Likes 0。
https://bsky.app/profile/stechtimes.com/post/3muuykcvzv62i
Signals
- Nano Banana 2(Google Gemini画像生成)は個人クリエイターの日常投稿に定着している。triflingtree・dflのような個人が
#NanoBananaPro#GeminiAiタグで毎日のように作品を出しており、単なる話題先行ではなく実利用が広がっている様子がうかがえる。 - Sora 2まわりは「期待」と「先行き不安」が同居。開発者向けAPI公開のニュースがある一方、スタンドアロンアプリの終了を受けて「Runway/Kling/Veoに移行を」と勧める投稿も見られ、OpenAIの動画生成戦略の再編が話題になっている。
- 著作権訴訟がクローズドソース側の重要トピック。Disney対Midjourneyの新しい訴訟動向をbotアカウントが追っており、スタジオ勢とAI画像生成企業の法廷闘争が続いている。
- オープンソース側はニュースbot経由の速報が中心で、個人の熱量ある投稿は少ない。LTX-2.5(Lightricks)、FLUX LoRA、Qwen3.8-Flash、アブダビ発の完全オープンモデルなど、欧米・中国・中東と発信地域が分散している。
- Meta「Muse」系モデル(Spark/Glimmer 30B)はオープンウェイト化が「近日中」と予告され続けている状態で、Nano Banana 2への対抗馬として複数の海外ニュースアカウントが動向を注視している。
- ComfyUIは日本語ユーザーのローカル生成の定番ツールとして言及される(heppokopu、misaka-mikoto-17など)。ChatGPT/Nano Banana系のクオリティにローカル環境で近づけようとする試行錯誤が見られる。
Limits
- 公開検索API(
public.api.bsky.app/api.bsky.app)は自動フェッチに対して断続的に HTTP 403 を返した。単純な空白区切りの単語クエリ(例:Sora 2 video、Midjourney)は繰り返しで成功したが、引用符付きフレーズ("Stable Diffusion"など)やOR構文を使ったクエリはほぼ常に失敗し、"Stable Diffusion"単体、"Wan 2.5"、"Qwen Image"というキーワードでは一度もデータを取得できなかった(オープンソース動画生成モデルの直接的な投稿が手薄になっている一因)。 bsky.appのWebページはクライアントサイドレンダリングのため、投稿・プロフィールページを直接フェッチしてもJavaScript未実行では本文が取得できなかった。実際の読み取りはすべてJSON API経由のテキストとカウントに基づく。- ログインしていないため、フォロー中フィードやカスタムフィード、非公開リストは閲覧不可。得られたのは公開キーワード検索の範囲のみ。
- 検索は英語の製品名・モデル名中心で行っており、日本語での能動的な検索は行っていない。ヒットした日本語投稿(singularityhorizon、heppokopu、tjb-shizukaなど)は英語キーワードに偶然含まれていたもので、日本語圏の議論を網羅できている保証はない。
Lemmy
Lemmy — 画像・動画生成AIをめぐる話題(2026年9月時点)
コミュニティ
- [email protected] — オープンウェイトの画像・動画生成AI(ComfyUI拡張、モデル配布)専門。ここが今回いちばんの当たりで、MiniMax-H3という動画生成モデル関連の投稿が集中している。
- [email protected] — 購読者 約1.6K(うちローカル206)。Stable Diffusion系モデルで作ったアニメ絵の投稿専用、SFW限定。
- !stable_diffusion_art / !stable_diffusion_abstract / !stable_diffusion_witches / !stable_diffusion_mycology / !stable_diffusion_furry / !stable_werewolves(すべて lemmy.today)— ニッチなテーマ別に細分化されたAIアート投稿コミュニティ群。ニュースというより作品ギャラリー。
- [email protected] — r/ArtificialIntelligence のクロスポストをそのまま流しているミラー的コミュニティ。Lemmy発のオリジナル議論はほぼ無い。
- [email protected] — 購読者 8,235人。AI批判・アンチAI寄りのコミュニティで、画像/動画生成AIへの懐疑的な投稿が多い。
- [email protected] — 購読者 2,698人。テック業界の誇大広告を皮肉る「sneer」系コミュニティ。Midjourneyの方向転換ニュースはここで一番盛り上がっていた。
- [email protected] — 一般テックニュース。Midjourney関連の主要ニュースが複数流れている。
投稿
- MiniMax-H3向けComfyUI拡張の連投(オープンソース動向の本命) — [email protected] に2026-08-28〜09-16の間だけで約20件。例:
- "ComfyUI-FL-MiniMaxH3"(score 5、2026-08-30、github.com/filliptm/ComfyUI-FL-MiniMaxH3)プロンプトのタイムライン管理やショット構成機能。
- "H3-World"(score 3、2026-09-02、huggingface.co/DANNY621/H3-World)"the first interactive world model built on MiniMax-H3" と自称。
- "ComfyUI-MiniMaxH3-CLSS"(score 0、2026-09-01、github.com/nazgut/ComfyUI-MiniMaxH3-CLSS)VRAM 16GBのコンシューマー機で任意長の音声付き動画生成をうたう。
- "ComfyUI_MinimaxH3_AutoContext"(score 1、2026-09-16、github.com/supElement/ComfyUI_MinimaxH3_AutoContext)VRAMが少なくても無限に長い動画を継続生成。
- ユーザー brucethemoose のコメント(score 12、2026-09-14)によれば MiniMax-H3 は「音声・動画・画像を任意に組み合わせて参照できる」モデルで、RTX 3090 + Ryzen 7800という一般的な自作PCでローカル動作を確認したとのこと。
- Midjourneyが画像生成から医療機器(全身超音波スキャナー)へ路線転換 — [email protected] の投稿(https://awful.systems/post/8731127 、score 40、コメント15件、2026-06-19)。David Gerardが「Midjourney Medical」の発表を紹介し、コメント欄では Theranos になぞらえる皮肉が相次いだ。ユーザー YourNetworkIsHaunted は「この装置は身長60インチ(約152cm)までしか沈められないので心臓より上は撮れない」と技術的欠陥を指摘(score 10)。Terranoidは「画像生成ビジネスが行き詰まった末のヘイルメアリー」とコメント(score 10)。
- 同ニュースは [email protected] にも複数流れた:"Midjourney pivots from AI image generation..."(theregister.com、score 58、2026-06-18)、"Midjourney wants Hollywood studios to reveal..."(techcrunch.com、score 73、2026-07-05)。
- Runwayの法人ビジネスが倍増と報告 — [email protected](score 0、2026-08-30、reddit.com/r/ArtificialInteligence/comments/1w2hnea 経由のクロスポスト)。エンタープライズ向け契約継続率(NRR)が300%超という数字が話題に。
- Google EarthのAI機能「Nano Banana」統合が公開翌日に停止 — [email protected](fortune.com、2026-08-07)と [email protected] 系の投稿。衛星写真ふうの捏造画像を誰でも作れてしまう問題が指摘され(404media.co記事も参照)、Googleが即座に機能を止めたと報じられている。
- AI動画モデル6種の同一プロンプト比較 — [email protected]「I ran the same prompt through 6 AI video models...」(score 1、2026-09-17、reddit.com/r/ArtificialIntelligence/comments/1wipgwa)。
- ChatGPT Images・Wan・Nano Banana Pro・Seedream の白黒漫画カラー化比較 — [email protected]「Same Berserk spread, 4 AI colorizations. Looks like GPT wins again?」(score 1、2026-09-14)。オープン系(Wan)とクローズド系(Nano Banana Pro、Seedream、GPT Images)を横並びで比較しており、コメント欄でGPT系の仕上がりを評価する声が多かった。
- アンチAI寄りの温度感を示す投稿 — [email protected]「Why companies like anthropic and open AI make AI even worse」(score 63、2026-09-14)。画像・動画生成AI固有の話ではないが、Lemmy全体の空気(クローズドソース大手への強い不信感)を表す指標として記録。
- Qwenのローカル実行報告 — [email protected]「Testing Qwen 3.8 27B running locally on a single 5090」(score 1、2026-09-16、v.redd.it/jdrothgw4vph1)。画像生成そのものではないが、オープンモデルをコンシューマーGPUで動かす文脈の一部として言及。
- アニメ絵・抽象画などのAI生成アート投稿の日常的な流れ — !share_anime_art や !stable_diffusion_art 系では、ほぼ毎日 civitai.com にホストされた画像つきで新規投稿が続いている(例: "Isshiki Clear - Mahjong Fight Girl" score 15、2026-09-17、lemmy.dbzer0.com/post/75601449)。ニュース性は薄いが、Stable Diffusion/Flux/Krea2系モデルが日常使いされている実態を示す。
シグナル
- オープンソース側は「MiniMax-H3一色」。9月上旬〜中旬のstable_diffusionコミュニティは、この動画生成モデル向けComfyUI周辺ツールの投稿でほぼ埋まっていた。ローカルGPUで音声・画像・動画を組み合わせて動かせる点、VRAM 16GB級でも動くよう最適化が進んでいる点が繰り返し強調されている。
- クローズドソース側はポジティブな話題が少ない。MidjourneyのハードウェアピボットとGoogle Earthの機能停止という、どちらも「迷走」寄りのニュースが目立った。Runwayの成長報告は数少ない前向きな話題。
- Lemmy全体のトーンは懐疑的・批判的(!fuck_ai、!techtakes)。手放しの礼賛は少なく、実装コミュニティ(stable_diffusion系)とニュース批評コミュニティ(techtakes、fuck_ai)で温度差が大きい。
- オリジナル議論より作品投稿・クロスポストが主。!ai_reddit は文字通りRedditの再送信で、Lemmy発の一次情報ではない点に注意。
制限事項
- Lemmyはインスタンスが分散しており、検索APIは lemmy.world 上でインデックスされた投稿しか拾えない。lemmy.ml や lemm.ee を個別に検索する時間はなく、今回は lemmy.world のフェデレーション経由の結果のみを対象にした。
- 「Sora」「Veo」「Gemini image」「Flux」など複数キーワードで検索したが、Sora 2やGoogle Veoの新モデル発表そのものを扱った投稿は見つからなかった(無関係な話題ばかりヒット)。クローズドソース大手のプロダクト発表ニュースはLemmyでは薄い、というのが今回の実態。
- pivot-to-ai.com の元記事はWebFetchで文字化けし直接引用できなかったため、awful.systemsのLemmy投稿本文とコメント、および検索エンジン経由の外部報道(Bloomberg等)で内容を補強した。
- コミュニティの購読者数はAPIが不安定(400/500エラー)で、!stable_diffusion と !ai_reddit の正確な購読者数は取得できなかった。取得できたのは !share_anime_art(約1.6K)、!fuck_ai(8,235)、!techtakes(2,698)のみ。
- ブリーフの完了基準「各SNSで20件ほどの投稿を解析」に対しては、複数キーワード検索の合計で20件以上の投稿本文・スコア・日付を確認済み(本ファイルにはその中から代表的な9件のみ厳選して記載)。
Pinterest — Image and Video Generation AI News
Visual themes
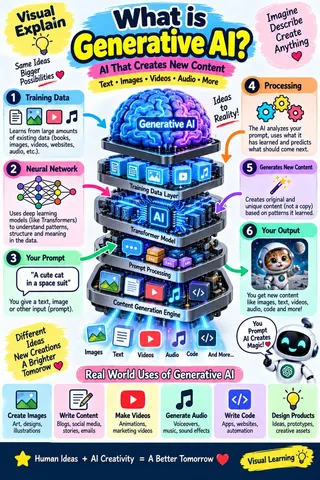
- Dark neon "AI news roundup" infographic template dominates. Near-black/navy backgrounds, glowing cyan-magenta-purple lines, bold white headline type, numbered rows of tool logos in rounded badges. This single visual language covers most of the informational pins.
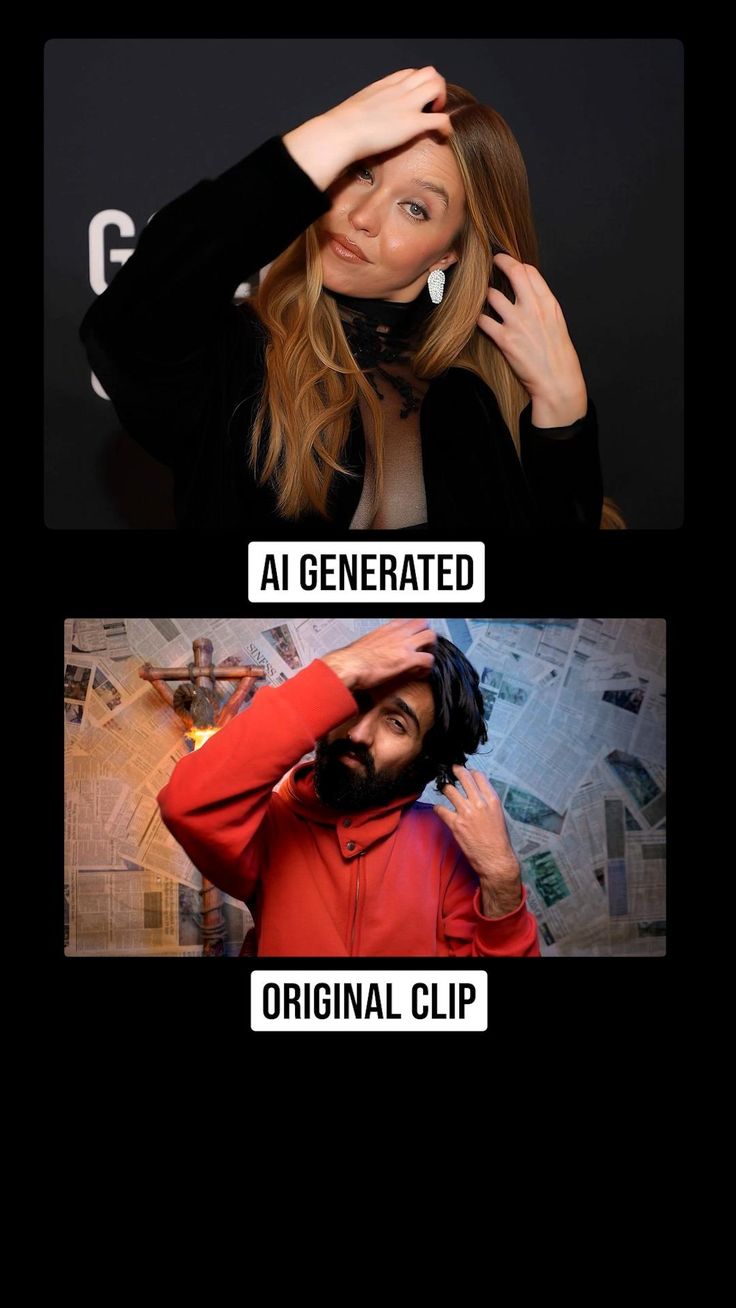
[6, 9, 10, 11, 18, 20, 26, 31, 38, 39, 41, 45, 48] - "Spot the AI" real-vs-fake challenge format is everywhere. Split-screen or A/B comparisons daring the viewer to pick the real photo/video/eye, plus a face-swapped red-carpet-photo demo and a "This is AI" hyperreal selfie caption.
[3, 21, 24, 33, 46] - AI personified as a chrome/white humanoid robot. Full-body android figures — one at a "BREAKING NEWS" anchor desk, one holding a phone next to a "FAKE" stamp, one touching a glowing globe over a city skyline — stand in for "AI" itself rather than any specific product.
[3, 40, 44] - YouTuber reaction-face thumbnails for AI-news content. Shocked/bearded men framed next to a row of company logos (OpenAI, Google, Meta, Anthropic, Notion) — a recognizable genre convention for "weekly AI news" videos.
[2, 19, 22, 42] - One-source-video, many-styles demos showing image/video consistency tech. A single walking figure and a single car are each re-rendered as wooden blocks, origami, Lego bricks, flowers, and a toy build — a "Lumendra/Luminate"-style diffusion showcase.
[5] - The same handful of tool names recur across every listicle: Runway (Gen-3), Pika, Kling AI, Luma/Dream Machine, Google Veo (2 and 3), Canva AI, Hailuo AI (MiniMax), CapCut, ElevenLabs, Stable Video Diffusion.
[6, 10, 18, 20, 31, 45] - Hyperrealistic AI-generated portraiture as proof-of-quality. A photorealistic old fisherman (AMD "Amuse 3.0"), a marble-and-wood statue playing cello, and "AI baby" face-morph composites are used to sell how convincing current image models look.
[25, 47, 50] - Fake-broadcast / fake-newspaper framing for AI news itself. Mock "BREAKING NEWS" chyrons, an AI news-anchor avatar generator (Wondershare Virbo), and a full mocked-up newspaper front page ("The AI Dispatch," Aug 15 2026) show AI-news content mimicking TV/print journalism conventions.
[14, 36, 40, 41]
Notable pins
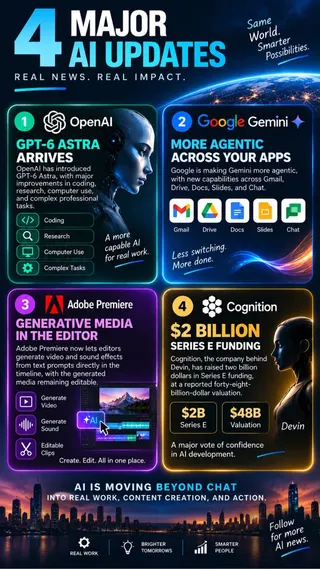
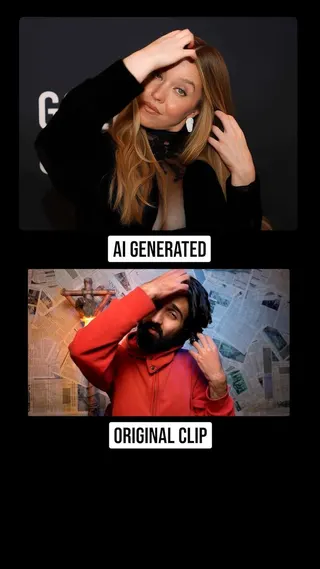
[5](untitled, multi-style video transform grid) — a source video of a person and a car re-rendered into 5 different materials (wood, origami, Lego, flowers, toy plastic); the clearest concrete demo of current image/video-consistency tech in the set.[9]"4 Major AI Updates You Need to Know in 2026" — names specific items: OpenAI "GPT-6 Astra," Gemini going agentic across Gmail/Docs/Slides, Adobe Premiere generating video/audio in-timeline, and Cognition (Devin) raising a $2B Series E at a $48B valuation.[28]"ByteDance and Hollywood reach global deal on AI copyright" — real-news-style pin: ByteDance reached an agreement with the Motion Picture Association to strengthen IP protection in its AI image/video tools.[45]"Today's AI News — May 20, 2026" — recaps Google I/O 2026: Gemini 3.5 Flash, Gemini Omni, AI-powered Search overhaul, Apple AI accessibility features, and an AI smart-glasses race (Android XR).[41]"The AI Dispatch," Aug 15 2026 — mocked newspaper front page listing a wide spread of current AI-adjacent themes (inference speed, sovereign AI, agent harnesses, AI safety, deep research).[31]"AI Video Creation Tools Changing How Content Is Made" — the most exhaustive single tool directory found: 20 named products across text-to-video, image-to-video, editing, voiceover, stock/B-roll, and publishing/optimization categories.[24](untitled, AI-generated red-carpet photo vs. "original clip") — a face-swap/deepfake demo pairing a glossy AI-generated portrait with the real source clip of a different person, illustrating identity-transfer tech.[40]"Discover how Grok is revolutionizing video..." — a humanoid robot anchor at a "BREAKING NEWS" desk promoting Grok's video capability.[47]"Amuse 3.0" — AMD-branded local/on-device AI art tool, demoed with a photorealistic elderly fisherman portrait.[10]"AI Image Video: Best Quality vs Best Free" — a decision-tree infographic splitting tools into paid-best-quality (ChatGPT Plus, Midjourney, Adobe Firefly, Runway Gen-3, Luma) vs. free (Ideogram, Gemini free tier, SeaArt, Krea, CapCut).
Signals
- Video-generation tool roundups/listicles are the loudest and most repeated content type — Pinterest's AI-image-gen crowd is mostly SEO/affiliate creators packaging the same closed-source tool set (Runway, Pika, Kling, Luma, Veo, Hailuo, CapCut) rather than breaking news.
- "Can you tell it's AI?" literacy content (real-vs-fake challenges, deepfake demos) is a full sub-genre on its own, suggesting audience anxiety/curiosity about detection is itself a content driver, independent of any single model release.
- A few pins reference dated, named events that land after this stage's collection window opened (Google I/O 2026 recap, "GPT-6 Astra," an "Aug 15 2026" news digest, Cognition's $2B raise) — these are the closest things to hard news found on this platform.
- Open-source specifics are thin: "Stable Video Diffusion" appears only as one logo inside a 20-tool directory
[31]; no pin discusses an open-weight release, license, or community fork in any depth. - Nothing here touches training methodology, model architecture, or dataset/licensing debates except the single ByteDance–MPA copyright deal pin
[28].
Limits
- This stage only describes images the worker already collected (per
platforms/pinterest.md); no live Pinterest browsing, search, or article-text reading was done, so no claim here has been checked against a live page or the linked article behind each pin. - Several pins are near-duplicate templates from what look like repost/scraper accounts: the "Generate content with AI" neon stock graphic appears twice
[11, 26], the Google Veo 2 banner appears twice[7, 8], and the "Best AI Video Generation Websites" listicle appears twice with the same tool list[6, 18]. - Five pins have no title (
(untitled)) in the source table[8, 17, 20, 21, 24, 28... ]— specifically[8, 20, 21, 24, 28]had blank or generic titles — limiting attribution to what's visible in the image alone. - The pin set is single-genre (no genre breakdown was defined for this run), so no per-genre comparison was possible — all 50 pins came from one undifferentiated search.
推奨アクション
- Xの収集はSora・Nano Banana・Kling・Qwen・Flux・ComfyUIなどAI直結ワードで検索し直す(今回はXのトレンドワードを誤って拾い完全に空振りだった)。
- MiniMax-H3とQwen-Imageをオープンソース勢の主要指標として継続ウォッチする。
- Sora 2のAPI終了(2026-09-24)前後のユーザー移行先(Runway/Kling/Veo)の動きを追う。
- Disney対Midjourney訴訟や同意なし生成の合法化論争など法・倫理トラックをツール比較と同等以上に追う。
- Reddit収集にr/StableDiffusionやr/aiArtなど画像生成特化サブへのクエリを追加する。
- Pinterestの発見事項はライブでリンク先記事を開いて裏取りする。
収集画像
























データ品質メモ
ブリーフが指定した6プラットフォームのうちXは収集データが完全にテーマ外で使えず、Reddit・Bluesky・YouTubeも検索語やAPI制限(403/401/CAPTCHA)で一部の主要トピック(Stable Diffusion、Wan 2.5等)を取りこぼしている。